make-it-betterAn Open-Source Skill That Improves Websites in Scored Rounds
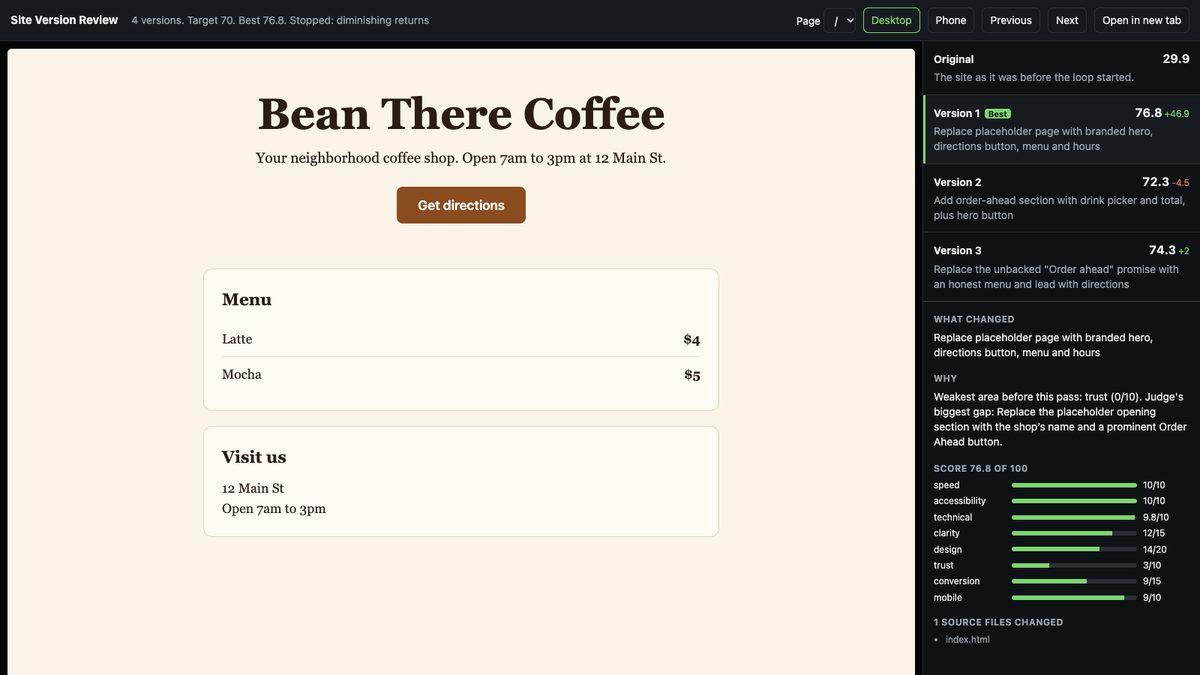
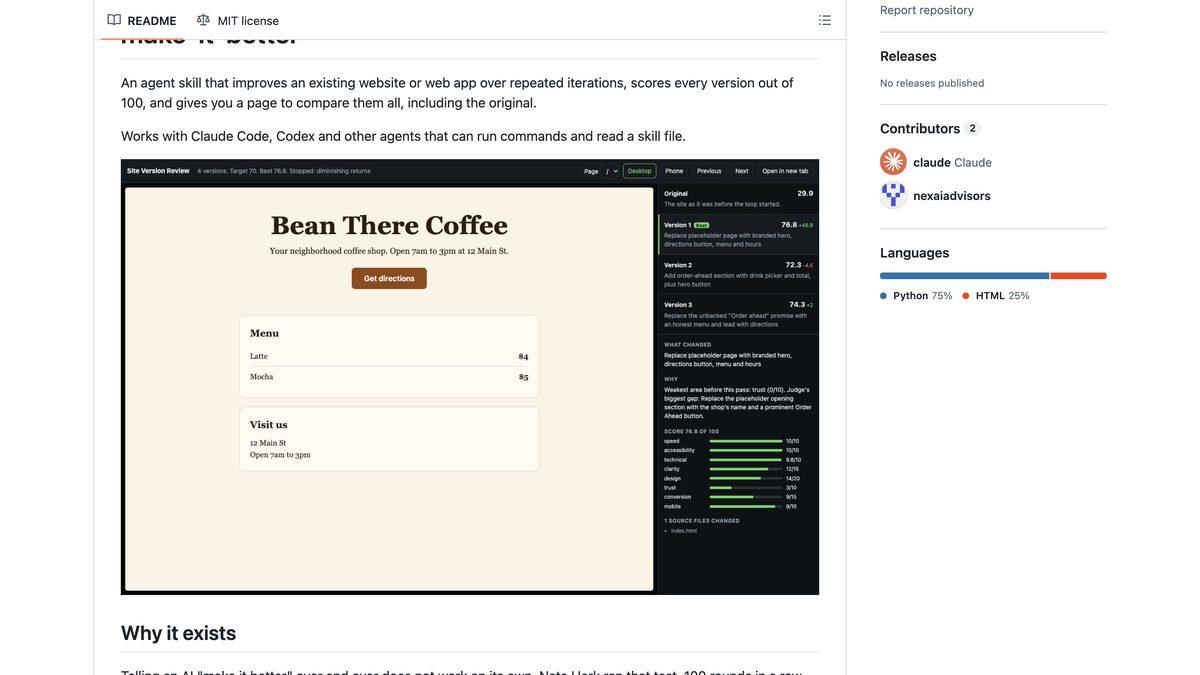
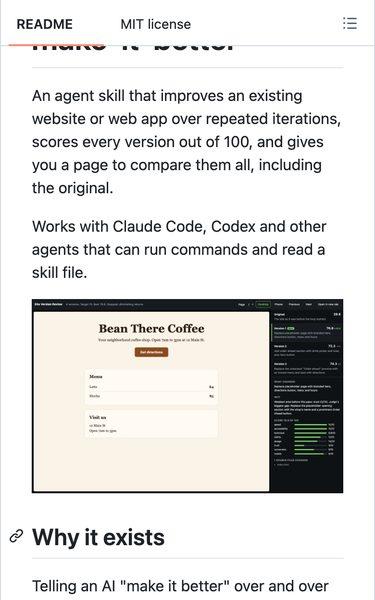
An agent skill for Claude Code, Codex and similar tools that improves an existing website over repeated rounds, scores every version out of 100, and opens a page to compare all of them against the original.
Built with Claude Code, Codex, Agent skills, Lighthouse, Python, agent-browser.
Out of 100
Every version scored by Lighthouse plus a separate judge
1 change
Per round, each on its own commit
What it is
Telling an AI to 'make it better' over and over tends to bloat a site until it breaks. make-it-better keeps the repetition and adds guardrails. Each round makes one focused change on its own branch, studies outside references first, and is allowed to change nothing or to remove things. A separate judge scores every version, so the agent that made a change never grades it. Scores combine Lighthouse with that judge. At the end the user gets a local review page with a button for every version, desktop and phone views, and a note on what changed and why, plus a branch with every version as its own commit and a '-best' branch at the top score. It never invents facts such as prices, reviews or customer names.
The problem
Repeated 'make it better' prompts make a model add code it does not need, never check other sites, and grade its own work. The result gets longer, not better.
What I built
One change per round, a separate judge, outside references before each change, an option to stop early at a target score, and a rule against invented facts. Every round is a commit, so any version can be restored.
What happened
Published as a public MIT-licensed repository with a companion article on the NexAI blog.
What it changed
- Turns open-ended AI edits into measured rounds that can be compared and rolled back
Who it fits
- Small-business owners improving a site built with an AI builder
- Developers who want measured, reversible improvement rounds
- Judge separated from the agent that made the change
- Review page comparing every version on desktop and phone
- Auto-stop at a target score, on diminishing returns, or on a regression
Want something like this built?
Bring the job that eats your week. Step 1 is a free 15-minute fit call. Step 2 is the AI Staff Assessment, $500, a written assessment you keep. Step 3 is your first hire at a published price, or you take the assessment and stop.